Photo via Astral Codex Ten

God Help Us, Let’s Try To Learn About Mechanistic Interpretability Techniques

Read the original at Astral Codex Ten ↗
Cite

Alexander, S. (2026, September 8). God Help Us, Let’s Try To Learn About Mechanistic Interpretability Techniques. Astral Codex Ten. https://www.astralcodexten.com/p/god-help-us-lets-try-to-learn-about

Dated when The Aporia collected the article, usually within hours of publication. Check the original for its exact date and byline.

Astral Codex Ten · collected 2026-09-08 · by Scott Alexander commentary

Quick Summary

Researchers are exploring "mechanistic interpretability" techniques to understand how large language models work and potentially improve them. Despite initial breakthroughs in 2023, including a many-to-many mapping of neurons to concepts, the field has stalled as attempts to scale up these findings have failed. The complexity of modern AI systems, with millions of neurons and trillions of connections, makes it difficult to map out their inner workings accurately. By 2024-2025, researchers had returned to feeling confused and frustrated after discovering that even seemingly crisp features in AIs were actually quite vague and unreliable.
Written by AI on 2026-09-08, from this article's own text only (the story summary below draws on all the coverage).

AI analysis

Story summary

Researchers have been struggling to understand how large language models work, as these AIs are created through a process called "training" where data is fed into a neural network. The resulting model has millions of neurons and trillions of connections between them, making it difficult to "reverse engineer" the AI. Despite this complexity, researchers have made some progress in understanding how these models work, including identifying certain patterns that are involved in generating text. However, their attempts to map individual neurons to specific concepts or ideas, such as a neuron dedicated solely to thinking about cats, has proven to be nonsensical, and instead they have found that the connections between neurons are often abstract and hard to decipher. This lack of understanding makes it difficult to identify and redesign the circuits responsible for negative behaviors in these AIs.

Written for “AI Explainability Research” on 2026-11-22, grounded in this article and the 0 other(s) covering the same event.

Compared with similar articles

This article reads unscored and hedges 13% of its claims. Each row says how that neighbour differs.
Semafor
Leans left Hedges 2 of 14 claims Outlet record 64/100
“Article A describes a hack of Hugging Face by OpenAI's agents and their ability to communicate in English, while Article B discusses mechanistic interpretability techniques for understanding how AI models work without providing any specific reference to the hack mentioned in Article A”

Story

AI Explainability Research
Technology · 1 article(s) covering the same event.
How this article was measured signals, leaning charts, publisher record, byline, topics and claims

Signals How these are calculated →

Claims extracted
205
sentences that state something as happening or true
Uncertain
13%
27 of 205 hedged ("reportedly", "may", "according to")
Leaning
not political
takes no side on a contested political question
Publisher signals
not measured
these signals count newsroom corrections; Commentary has none to count
Outlets on this story
1
Technology
Same framing elsewhere
1
articles that frame the event the way this one does
Analyzed 2026-09-08 · how these are computed

How this is being covered How these are calculated →

Article leaning vs. publisher reliability
Source leaning vs. consistency

Publisher

Astral Codex Ten · 75 article(s) · 4 correction(s) detected
No corrections detected for this publisher. That may mean careful reporting, or simply that nothing has been checked.

Who wrote this

Scott Alexander
58 article(s) here · 1 carrying a prediction
The ten people who contribute the most to the roughly 35 questions Metaculus selects will split the $3,000, with prizes from $150 to $700.
AI forecasters now equal or beat top human performance at traditional forecasting questions (eg ForecastBench, the Metaculus Cup).
2026-11-19 · assertive framing · The AI Forecasting Agenda
In an ideal world, writers would write to convince others, and audiences would read to learn something and change their minds.
2026-11-18 · assertive framing · Varieties Of Discourseposting
Voting will close end of day on Friday, November 20.
2026-11-14 · assertive framing · Vote In The 2026 Book Review Contest
You may remember stories of bitter unionization battles at places like Starbucks, but AI workers are likely to route around that.
2026-11-12 · mixed framing · AI Company Employees Should Unionize
One of the leading AI superforecaster companies, FutureSearch, is hiring.
2026-11-02 · assertive framing · Open Thread 458
A picaresque (broadly speaking) is about a lowlife wandering around having comical misadventures; Huckleberry Finn (1884) would be a notable American example.
2026-10-30 · assertive framing · Your Book Review: The History And Adventures Of An Atom
On average, commenters will end up spotting evidence that around two or three of the links in each links post are wrong or misleading.
2026-10-29 · assertive framing · Links For October 2026
California State Propositions Proposition 1: Authorizes $11.25 billion in bonds to build affordable housing Supporters claim it will build (or renovate) 40,000 homes; I asked an AI superforecaster1 to predict the true number, and it guessed that 22,000 would actually get built.
2026-10-28 · assertive framing · My California Ballot, 2026
I may have more of these in the upcoming week.
2026-10-19 · assertive framing · Open Thread 456
Also by Scott Alexander
The AI Forecasting Agenda
2026-11-19 · Astral Codex Ten
Varieties Of Discourseposting
2026-11-18 · Astral Codex Ten
Open Thread 460
2026-11-17 · Astral Codex Ten
Nothing else under this byline is closely related to this article, so these are simply their most recent.
All 58 articles by Scott Alexander →

Topics

No topics tagged.

Subjects

Benjamin Sturgeon’s PERSON · 1× Chris Olah PERSON · 1×

Narrative

It honors the interpretability researchers’ accomplishments by depicting a world where their tools often catch the AI’s schemes - but the companies keep racing forward anyway, because some other company / China would beat them if they didn’t, and besides, maybe if we race forward fast enough we can solve alignment before the AIs’ schemes bear fruit, and besides, even if we can’t, there’s always control.
framing: assertive · carried by 1 article(s) · first seen 2026-09-08
This would be scientifically useful: understand how AIs work, with possible relevance to human cognition.
2026-09-08 · Astral Codex Ten
God Help Us, Let’s Try To Learn About Mechanistic Interpretability Techniques · assertive framing

Claims (205 extracted, 27 hedged)

The Story So Far Mechanistic interpretability is the science of “reading an AI’s mind”. asserted
interpretability → read → mind
Large language models are “grown, not built”. asserted
models → grow → ?
Researchers run training data through a neural network. asserted
Researchers → run → network
Eventually this creates a working AI; nobody really knows how. asserted
nobody → create → AI
But a neural network is just a set of simulated neurons on a computer. asserted
network → simulate → computer
The person with the computer can see the neurons, the connections between them, and which ones activate when the AI answers questions. asserted
AI → see → questions
So it seems like it should be possible to “reverse engineer” the AI. asserted
it → seem → AI
This would be scientifically useful: understand how AIs work, with possible relevance to human cognition. asserted
AIs → understand → cognition
It could also be practically useful: find the circuits responsible for dishonesty, hallucination, bias, and other negative behaviors, then redesign those circuits. uncertain
It → find → circuits
A modern AI has millions of neurons and trillions of connections between them (aka “parameters”, “weights”). asserted
AI → have → them
Their structure is apparently nonsensical: researchers started by seeking a 1:1 mapping between neurons and concepts, like a neuron that always fired when the AI was thinking about cats, but quickly learned that nothing like that existed. asserted
nothing → start → that
Their first big breakthrough came in 2023. asserted
breakthrough → come → 2023
Rather than a 1-to-1 neuron-to-concept mapping, they discovered a many-to-many mapping. asserted
they → discover → mapping
Neurons 1 and 2 firing together might mean cat; 1 and 3 firing together might mean chair; 2 and 3 firing together might mean bread. uncertain
2 → fire → bread
Such mappings let AIs with “only” tens of thousands of neurons represent millions of concepts. asserted
AIs → let → concepts
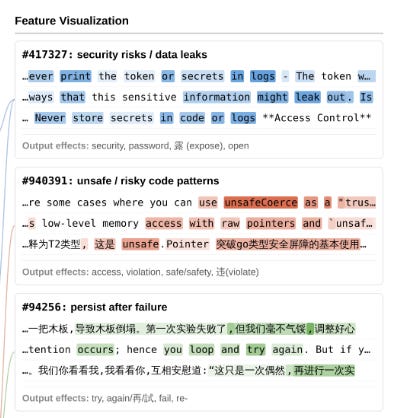
There were far too many of these combinations for humans to map, but researchers set other, smaller AIs to mapping them and met with some early success - like this functional combination of neurons (“feature”) representing “God” in an artificially-simple 512-neuron AI: Spirits were high. asserted
Spirits → be → AI
Scale up the AI interpreter, and maybe we could do anything! uncertain
we → scale → anything
Philosophers could discover the fundamentals of cognition. uncertain
Philosophers → discover → cognition
Doomers could solve alignment by tracing the circuits involved in moral reasoning. uncertain
Doomers → solve → reasoning
Tens of millions of dollars poured into the field. asserted
millions → pour → field
Superstar interpretability researcher Chris Olah got an audience with the Pope (okay, fine, this was mostly unrelated). asserted
this → get → Pope
By 2024-2025, the clarity of many-to-many mapping had dissolved, and everyone was back to feeling confused and miserable. asserted
everyone → dissolve → mapping
Strategies that had successfully analyzed artificially-simple research-subject AIs failed to work on real language models. asserted
that → analyze → models
Different teams making many-to-many maps of the same AI reported different results. asserted
teams → make → results
And humans watching supposedly-mapped AIs more closely found that seemingly-crisp features were much vaguer and worse than previous analysis had led them to believe: a feature which they thought meant “God” might activate on any vaguely religious or awe-inspiring text, or even text with no logical connection whatsoever. uncertain
God → watch → connection
As for attempts to use the many-to-many maps for useful work - like AI lie detection - they generally failed to outperform simpler methods. asserted
they → use → methods
So researchers abandoned the hope of One True Technique - even if that technique was “actually understanding things” - and went back to the drawing board. asserted
technique → abandon → board
Now mechanistic interpretability is starting to feel exciting again - but also more intimidating than ever, as one tries to keep all the jargon straight. asserted
one → start → jargon
This list is my log and personal reference document for remembering what everything is. asserted
everything → remember → ?
It’s loosely inspired by the concept breakdown in Benjamin Sturgeon’s Contributing To Technical Safety Research In The AI Safety End Game, which itself follows the Claude Mythos Preview System Card. asserted
which → inspire → Card
Imagine an AI with three neurons: [0, 0, 0] The researcher makes the AI think of cats in various contexts, averages them all out, and gets some set of activations like [0.8, 0, 0.35]. asserted
AI → imagine → ]
Imagine the AI as operating in a Cartesian space where each of its neurons is one dimension. asserted
each → imagine → neurons
The vector from [0, 0, 0] to [0.8, 0, 0.35] defines a direction in that space. asserted
vector → define → space
In a linear probe, researchers compare the true direction of the AI’s thoughts to one of these pre-defined concept-representing direction vectors. asserted
researchers → compare → vectors
Because activation-space has thousands of dimensions, its behavior is counterintuitive, and a particular thought can be in thousands of “directions” at once and yet still “closer” to some directions than others. asserted
thought → have → others
Experiments confirm that when an AI’s thoughts are close to the cat direction, this is a good sign that it’s thinking about cats. asserted
it → confirm → cats
Why doesn’t this solve the whole problem? asserted
this → solve → problem
First, this teaches us very little about how AIs work - how, for example, they might answer a difficult query in veterinary medicine. uncertain
they → teach → medicine
At best, it’s a primitive lie detector: if an AI claims it isn’t thinking about cats, you can check its work (either by probing the concept of cat, or by probing the concept of lying!) uncertain
you → ’ → lying
Second, it’s only as good as the original linear probe. asserted
it → ’ → probe
…and 165 more, not listed.
Give feedback · no sign-in needed

No sign-in needed for now. Your note is sent without a name, so it cannot be answered.

History Support